AWS · Serverless · Platform Architecture

Abuja, Nigeria

Most SaaS platformsfail because theright infrastructurewasn’t built.

Deploy velocity drops

Releases that used to ship weekly now take weeks, and everyone holds their breath.

Ugochukwu Oguejiofor

Senior Software Engineer

Ugochukwu OguejioforAbuja, Nigeria

AWS · Serverless · Platform Architecture

When a SaaS platform struggles. The underlying architecture is the problem.

Most engineering leaders I work with reach out when deployments slow down, AWS spend outpaces growth, and every new feature feels like a rewrite.

The issue usually isn't the tools, it's the architecture underneath them.

the pattern

When platforms start to creak

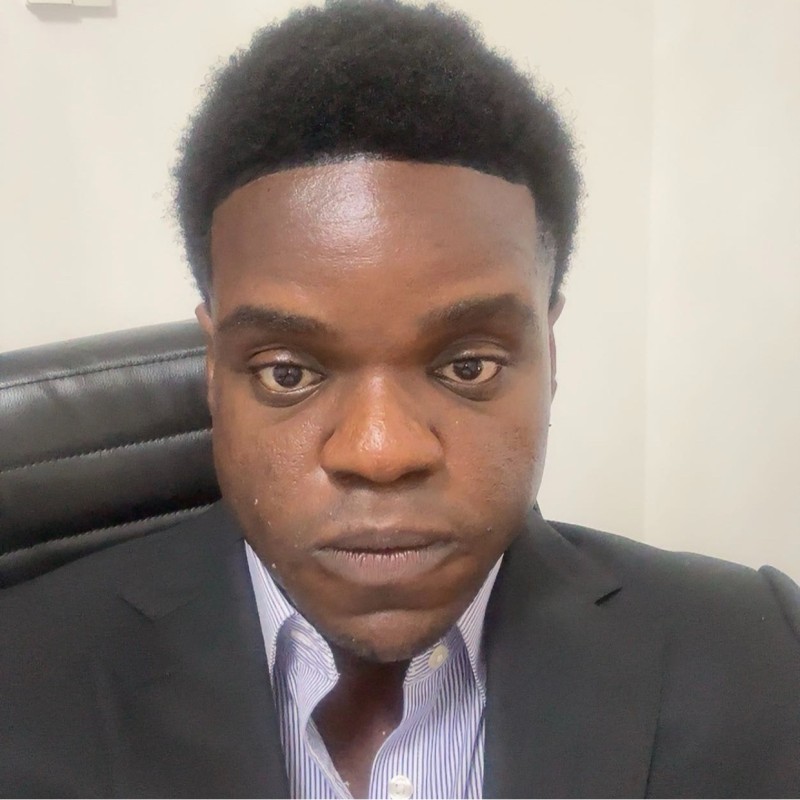
Portrait of Ugochukwu Oguejiofor, AWS platform architect specializing in Terraform, ECS, and SaaS production readiness

I work with engineering teams on AWS, SaaS platforms, regulated workloads, high-traffic consumer apps, who've outgrown the architecture that got them to product-market fit.

The symptoms look different everywhere: runaway Lambda bills, brittle multi-tenant isolation, deployment pipelines nobody trusts, or GenAI features that work in demo but not in production. The root cause is usually the same: structure that wasn't designed for where the product is heading.

Principles I work from

Symptoms lie; structure tells the truth

Runaway Lambda bills, brittle deploys, and audit gaps often look like separate fires. They're usually one structural debt showing up in different places.

Fix shape before tuning knobs

Right-sizing instances or adding alarms helps after boundaries are clear. Before that, you're optimizing a system nobody can draw from memory.

Honest scope beats heroic execution

If the problem is operational or someone else is a better fit, I'll say so. The engagement only works when the diagnosis is real.

Signals I hear most often

AWS spend climbs faster than user growth

Every feature touches too many services

Multi-tenant or compliance requirements expose design gaps

how i work

Diagnosis before build

Every engagement follows the same sequence. I don't start with a tool list or a fixed deliverable, I start with what's actually breaking and why.

  1. Listen

    You describe the symptoms in your words: slow deploys, climbing AWS bills, audit gaps, tenant isolation worries. No job spec required.

  2. Map symptoms

    I trace how the symptoms connect, what touches what, which environments fail first, where the team holds its breath before a release.

  3. Diagnose root cause

    Separate surface fixes from structural debt. The goal is an honest read: architectural, operational, or something a different specialist should own.

  4. Prioritize fixes

    Rank remediation by blast radius, effort, and dependency order. Quick wins get called out separately from changes that need the platform reshaped.

  5. Implement with the team

    Hands-on where it matters, Terraform modules, deploy gates, isolation proofs, paired with your engineers so the pattern sticks after I leave.

fit check

Who I work best with

I'm selective about engagements. The work goes best when the problem is structural, not when someone needs another pair of hands to execute a fixed spec.

Good fit

  • SaaS teams on AWS who've found product-market fit but are paying an architecture tax
  • Engineering orgs of 5 to 20 where deploy confidence is dropping faster than feature output
  • Regulated or multi-tenant products where isolation, compliance, or routing can't be bolted on late
  • Leaders who want a diagnosis before a build, honest about whether I'm the right person

Not a fit

  • Greenfield MVPs with no users yet, structure problems need something to structure
  • Body-shop contracts where the spec is fixed and architecture isn't in scope
  • Frontend-only or design-only work disconnected from the platform underneath

where structure was the fix

Case studies

Each engagement started with a symptom. The work was finding the structural problem underneath it.

Regulated SaaS client

The situation

A regulated SaaS client ran ECS Fargate services across development, staging, and production. Several workloads were batch-oriented or used only during business hours, but every service maintained a steady desired count 24/7. AWS spend climbed without a matching jump in active users or tenant volume.

ECS Fargate Cost Reduction

ECS Fargate ran around the clock in environments that only needed capacity during business hours.

The diagnosis

The problem wasn't Fargate itself, it was a deployment default. Workloads were provisioned for peak availability even when peak never arrived outside a narrow window. Right-sizing instance sizes wouldn't help if the services stayed running when nobody was using them.

Measurable result

  • Material

    Recurring AWS spend cut

  • Scale-to-zero

    Scheduled on bursty workloads

  • 0 rewrites

    Application code unchanged

Read the full case study →

Regulated SaaS client

The situation

The client operates a regulated SaaS product on AWS commercial and GovCloud partitions. The product needed the same deployment discipline in both, multiple environments, strict change control, and FedRAMP-aligned infrastructure, without maintaining two unrelated Terraform codebases.

Six-Environment Terraform and GovCloud Management

Commercial AWS and FedRAMP GovCloud had to share platform patterns, not copy-pasted Terraform.

The diagnosis

The team didn't need more Terraform files, they needed a platform shape: shared modules with environment-specific overlays, partitioned state, OIDC-federated deploys, and an explicit gate before production changes landed.

Measurable result

  • Multi-env

    Terraform platform with OIDC deploys

  • FedRAMP

    GovCloud deployment to production

  • OIDC

    Short-lived CI credentials, no static keys

Read the full case study →

Regulated SaaS client

The situation

Each new environment, dev sandbox, staging replica, customer-specific partition, required an engineer to hand-assemble Terraform, apply in the right order, configure secrets and DNS, and manually verify that services came up correctly. A routine request blocked a senior engineer for days.

Environment Onboarding Under 30 Minutes

Spinning up a new environment took days of manual Terraform, config, and verification.

The diagnosis

Environments weren't a platform capability, they were a craft project. Without composable module layers and an automated apply-and-verify pipeline, every new environment repeated the same two-day ritual with slightly different mistakes.

Measurable result

  • <1 hr

    Environment onboarding time

  • Days →

    Previous manual process eliminated

  • Multi-env

    On the same modular platform

Read the full case study →

Rose Digital · New York Lottery

The situation

The New York Lottery mobile and web apps ran on a serverless backend with more than 100 Lambda functions covering SSO, administration, games, retailers, ticket scanning, notifications, and content management. As traffic and features grew, the architecture became harder to maintain and extend.

Production Platform with 100+ Lambda Functions

A high-traffic public app was running on 100+ Lambdas with no domain boundaries and deploy risk on every release.

The diagnosis

This wasn't a 'too much serverless' problem, it was a boundaries problem. Functions were grouped by history, not domain. Dependencies were bundled monolithically, inflating cold starts. IAM was wider than any single function needed because nobody had mapped least privilege per boundary.

Measurable result

  • 100+

    Lambdas across bounded domains

  • Split-stacks

    Nested stacks under CloudFormation limits

  • Cold starts

    Reduced via layered dependencies

Read the full case study →

Regulated SaaS client · Dittofi

The situation

A regulated SaaS client needed multi-tenant isolation at the infrastructure layer: path-based tenant routing, edge auth, and an API layer that couldn't trust the network between CloudFront and Lambda. Separately, Dittofi needed non-engineers to ship production apps with isolated customer environments, not a shared runtime with a tenant_id column.

Multi-Tenant SaaS Architecture

Tenant isolation lived in application code, and every new customer or compliance rule became a custom infra project.

The diagnosis

Multi-tenancy has to be an infrastructure concern, not a middleware afterthought. Routing, auth, and storage boundaries need to be enforced before requests reach business logic, especially in regulated workloads.

Measurable result

  • Edge routing

    CloudFront + Lambda@Edge tenant paths

  • Isolated envs

    Per-customer generated deployments

  • Zero-trust

    Auth enforced edge-to-API

Read the full case study →

Rose Digital · New York Lottery

The situation

The New York Lottery platform served millions of public users through mobile and web apps, with an internal admin console for operators managing games, retailers, and user lifecycles. Authentication had grown service-by-service: inconsistent token validation, no shared SSO, and admin actions with no durable audit trail.

Cognito SSO, RBAC, Audit Logging, and Security Controls

Legacy auth across a public app left no central identity model, and the admin console had no audit trail.

The diagnosis

Auth wasn't a feature gap, it was an architecture gap. Without a central identity provider, every Lambda reimplemented verification differently. Without RBAC and audit logging at the API layer, the admin console was a liability waiting for a compliance questionnaire.

Measurable result

  • Cognito SSO

    Multi-tenant identity replaced legacy auth

  • RBAC

    Role-gated admin operations

  • Audit log

    Durable trail on Aurora Serverless

Read the full case study →

View all case studies on one page

from clients

What teams say after the structure is fixed

Real feedback from long-term engagements, cloud platforms, zero-to-production builds, and projects where accuracy mattered.

Long-term cloud platform partnership
“Ugo is an excellent engineer who has consistently produced top-quality deliverables for us over the past five years. He's reliable, communicative, and brings a strong problem-solving mindset to every project. We wouldn't hesitate to recommend him or to work with him again in the future.”

— Kurt, Kenyan Central Bank

Zero-to-production platform launch
“Ugo was professional and friendly in all interactions. He did quality work for our needs and available resources. He is a very skilled engineer and also shows aptitude for continual improvement in his craft. It was an overall great experience and Ugo did an excellent job to play a large part in successfully taking our project from zero to production. It was a pleasure working with him and we would definitely do it again in the future.”

— Evan, Rose Digital

Cloud project under deadline pressure
“Great communicator and an even better developer. Ugochukwu was able to provide exactly what we wanted within half the expected delivery date. Would highly recommend for his amazing work.”

— Alexi, Tissimo

AWS infrastructure requiring precision
“If you have cloud-based projects that require expertise and accuracy, Ugo is that guy! Very knowledgeable and trustworthy. Would recommend to anyone.”

— Benjamin, Extra Brain

recent

Latest field notes

Essays on the structural problems behind common AWS failures, not hello-world tutorials.

applied after the diagnosis

Capabilities

The stack is never the point. These are the tools I reach for once the structural problem is clear.

Languages

  • Go
  • TypeScript
  • JavaScript
  • Python
  • SQL

Cloud & Serverless

  • AWS Lambda
  • API Gateway
  • ECS Fargate
  • Aurora / DynamoDB
  • S3
  • CloudFront
  • Lambda@Edge
  • Cognito
  • SES
  • EventBridge
  • SQS / SNS

DevOps & IaC

  • Terraform
  • Serverless Framework
  • GitHub Actions (OIDC)
  • Azure DevOps
  • CircleCI
  • Docker
  • LocalStack

AI / ML

  • AWS Bedrock (Claude, Nova)
  • LLM evaluation pipelines
  • AI security
  • Prompt engineering
  • Prompt-injection mitigation
  • OpenAI

Frontend

  • React
  • Next.js
  • Redux Toolkit
  • React Native
  • Electron
  • Tailwind CSS

results

Outcomes

  • Restructured platforms serving enterprise and public-sector customers
  • Delivered FedRAMP-aligned GovCloud infrastructure to production
  • Cut recurring AWS spend materially through structural changes, not band-aids
  • Architected multi-tenant SaaS backends that survived compliance audits
  • Shipped production GenAI on Bedrock with defense-in-depth security
  • $100,000+ in long-term engagements from teams who needed the structure fixed

background

Education

MSc (Merit)

Newcastle University, United Kingdom

B.Tech (Hons)

Federal University of Technology Owerri, Nigeria

Best Graduating Student

verified

Credentials

As seen on Upwork

9,600+ hours · 100% client satisfaction

Independently audited cloud delivery on Upwork, with a perfect client satisfaction score.

View Upwork profile

from the field

Architecture field notes

Essays on the structural problems behind common AWS failures, runaway bills, brittle deploys, cold starts that won't quit, not another hello-world tutorial.

next step

Request an AWS Assessment

Describe the structural problem, not a job spec. I'll reply within 48 hours with an honest read on whether the issue is architectural, operational, or something else entirely.

What happens next

  1. 1.I reply within 48 hours with an honest read on your situation.
  2. 2.If it's structural, we'll schedule a free 30-minute scoping call, not a sales pitch.
  3. 3.If it's operational, the wrong stack, or someone else is a better fit, I'll tell you that too.

Request an AWS Assessment

We'll start with a free, no-obligation 30-minute scoping call.

Do not include AWS credentials, API keys, production secrets, or confidential customer data. A repository link or architecture diagram is enough for a first read.

We'll start with a free, no-obligation 30-minute scoping call.

Do not include AWS credentials, API keys, production secrets, or confidential customer data. A repository link or architecture diagram is enough for a first read.